Warehouse & logistics
- Pick, scan, pack
- Box handling and palletizing
- Sorting and shelving
- Barcode and label work
Egocentric data for physical AI
Global-shutter stereo, IMU, hand pose and action labels, recorded by real workers in real workplaces. Delivered in LeRobot, MCAP or HDF5.
For imitation learning, VLA pre-training and co-training, world models and hand–object interaction research.
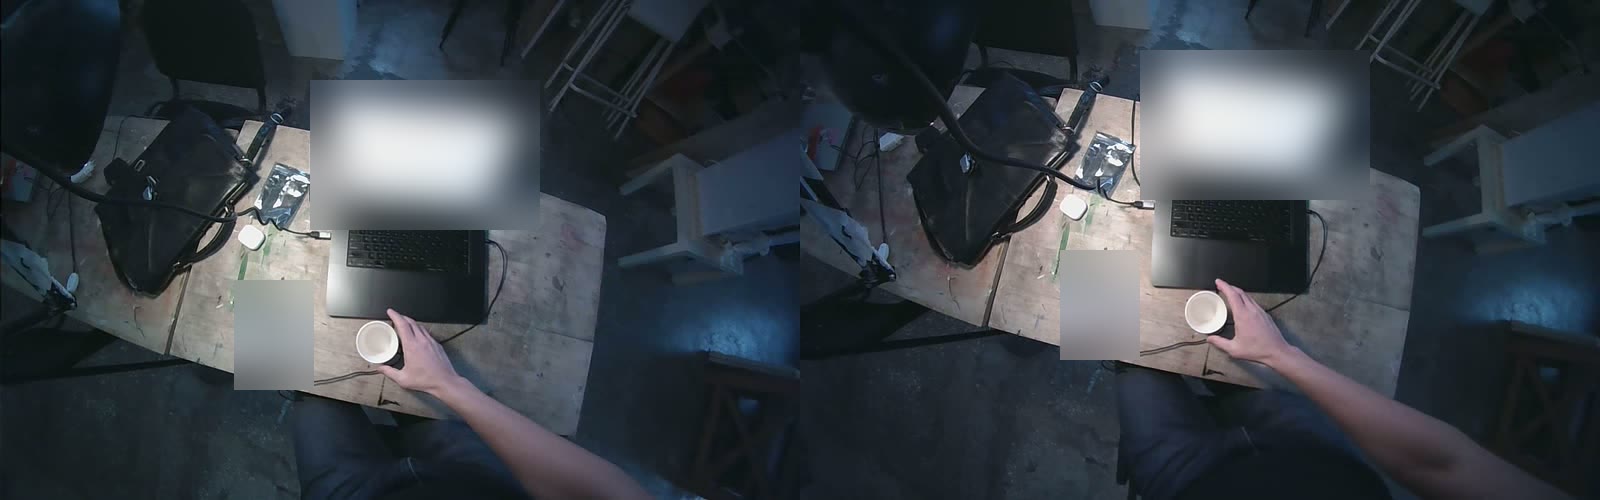 Early test capture
Where we capture
We have access to working sites and record people doing their actual jobs, with written consent. Tell us the task; we find or arrange the environment.
Need another environment — retail, home cleaning, light assembly? Ask us.
What's in every episode
Two global-shutter cameras, 1920 × 1200 each, 30 or 60 fps, wide field of view.
21 keypoints per hand, per frame, with confidence.
Task, sub-task and action boundaries with short natural-language descriptions.
Task spec, outcome (success / failure), environment, operator ID, device and capture settings.
Per-episode check of frame count, dropped frames, timestamp continuity and file integrity.
On-board accelerometer and gyroscope, hardware-timestamped against each frame's exposure.
Stereo depth and 6-DoF head trajectory for calibrated captures.
Object tracks, segmentation, contact events or your own label schema.
See the data
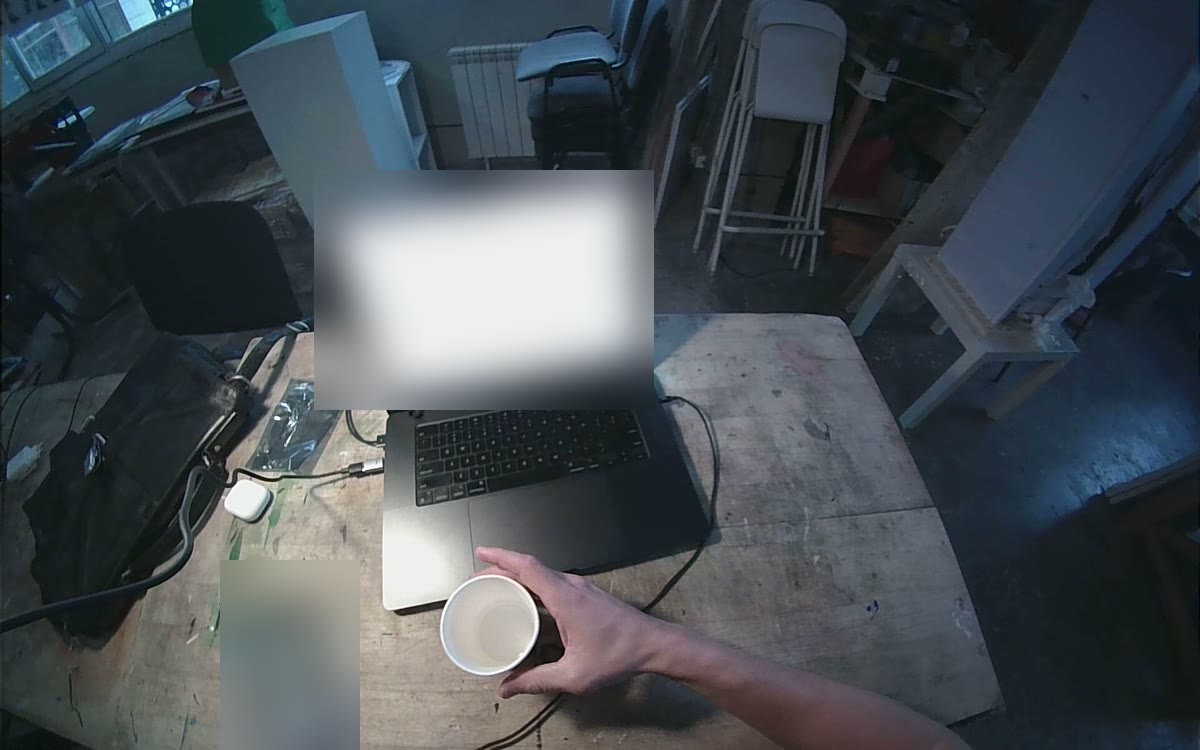 Raw left camera · early test capture
Panels show the delivery format. The full warehouse sample episode is in production. *IMU layer in validation.
Capture rig
A lightweight head-mounted camera tethered to a belt recorder. Workers keep their hands free and their normal pace.
| Sensors | 2 × AR0234, global shutter |
|---|---|
| Resolution | 2 × 1920 × 1200, side-by-side |
| Frame rate | 30 or 60 fps |
| Field of view | ≈ 144° horizontal, ≈ 92° vertical |
| Inertial | 6-axis IMU (accelerometer + gyroscope) |
| Sync | Hardware-synchronized stereo |
| Recording | Lossless raw or high-bitrate H.265 |
How we work
You define the task, environment, layers, volume and format. We propose a capture protocol.
A 10-hour pilot delivered in 2–3 weeks, so you can test the data in your pipeline first.
More operators, sites and hours on the same protocol, with QA on every episode.
Formats & delivery
Delivered via S3, Hugging Face (private) or physical drive. Calibration files and a data card are included with every delivery.
Consent & licensing
FAQ
Human demonstrations, recorded from the worker's point of view. Teams use it for pre-training and co-training alongside their own robot or teleoperation data. We do not collect robot joint states or teleoperation.
Yes. Send us the task definition, objects and success criteria. We write a capture protocol, agree it with you, and record against it — including your own items shipped to the site if needed.
Per accepted hour, depending on the environment, the layers you need and exclusivity. We quote after the spec and always start with a pilot.
Every delivery comes with a commercial training licence. Exclusive collections — recorded only for you and never resold — are available.
Everyone we record signs a written consent for AI-training use. Bystanders' faces and screens can be blurred, and we can avoid sensitive areas on site. Consent records are kept and available for audit.
A pilot typically takes 2–3 weeks from an agreed spec, including on-site capture, processing and QA. Larger volumes are scheduled per project.
Send the task, environment, layers, volume and format you need. We reply within one business day with a capture plan and a sample.
emil@vayta.tech